At the Industrial AI Summit 2026, industry leaders converged to discuss a critical inflection point in pharmaceutical manufacturing: the "Sensor-to-Decision" gap. While manufacturers have made strides in digitizing their factory floors, the regulatory scrutiny surrounding how this data is ingested, processed, and utilized by Artificial Intelligence (AI) remains a significant hurdle.
The session, titled "You Closed the Sensor-to-Decision Gap. FDA Will Ask You to Explain It," sparked a flurry of follow-up questions from attendees. Because of the technical complexity and the high stakes involved in pharmaceutical compliance, a panel of experts—including Adam Procopio, Scientific Associate Vice President at Merck, and Kristen Sauter, President and General Manager of Life Sciences at Adlib Software—provided deeper insights into the realities of document integrity. This report, the first in a two-part series, examines the tension between legacy document management and the rigorous requirements of modern AI-driven compliance.
The Core Dilemma: CDMO Accountability vs. Digital Reality
One of the most pressing questions from the audience addressed the "document accountability" paradox. As pharmaceutical companies increasingly rely on Contract Development and Manufacturing Organizations (CDMOs), the challenge of maintaining data integrity becomes dispersed.
The attendee query was direct: "Adam, you said you own the document accountability. But you also cannot control how a CDMO produces the record. So do you push your requirements into the quality agreement or accept the PDF and absorb the work?"
The "Prevention vs. Remediation" Trade-off
Adam Procopio of Merck acknowledges that the ideal scenario is proactive rather than reactive. "We certainly want to push digital data requirements into our quality and technical agreements whenever possible because prevention is better than remediation," Procopio explained.
However, the pharmaceutical landscape is defined by a vast, heterogeneous ecosystem of partners, each operating at different levels of digital maturity. For a global leader like Merck, waiting for every CDMO to achieve the same level of structured data output is not a viable strategy for rapid AI adoption. Consequently, the industry is forced into a hybrid approach: demanding higher standards in agreements while simultaneously investing in robust "ingestion engines" capable of handling fragmented formats—spreadsheets, scans, and PDFs—without losing the thread of traceability.
The Role of the Accuracy Layer
Kristen Sauter, President and General Manager of Life Sciences at Adlib Software, views this from the architectural perspective. According to Sauter, the technology required to handle these disparate inputs acts as a "document accuracy layer."
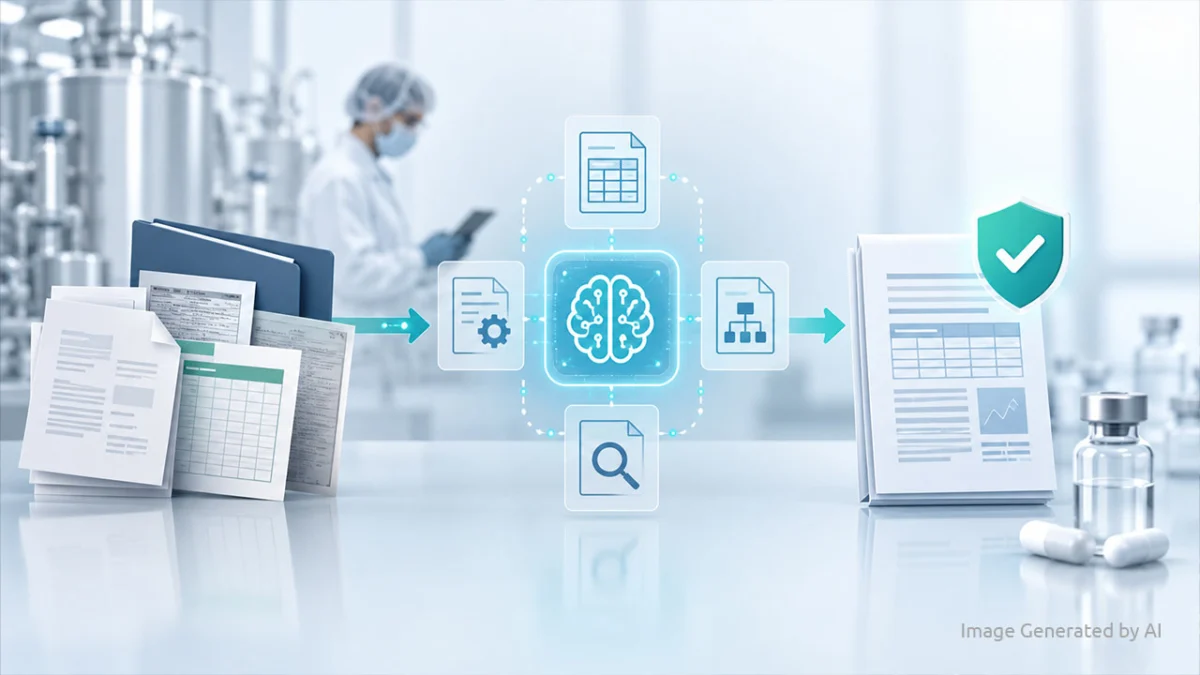
"The key architectural requirement is that the transformation from whatever format you receive to a normalized, AI-ready output must itself be auditable," Sauter stated. She argues that the failure of current systems often stems from a lack of visibility during the ingestion phase. Organizations must be able to demonstrate a clear chain of custody: the raw receipt, the system’s transformation logic, the final input into the AI workflow, and the confidence score of the extraction.
Traceability: The Great Debate Between Generation and Receipt
The question of where traceability should start—at the point of generation (the CDMO floor) or the point of receipt (the sponsor’s quality department)—is a point of contention that carries massive implications for regulatory audits.
The Myth of Retrofitting Traceability
Sauter is clear on the limitations of "receipt-only" traceability. "Traceability retrofitted at receipt is always incomplete," she warns. When a batch record travels across organizational boundaries—from a CDMO to a sponsor or from a manufacturing site to a regulatory submission—the original "generation context" is frequently stripped away.
In a traditional workflow, the metadata—the digital fingerprints of approval, authorship, and system provenance—is lost the moment a document is converted into a static PDF. You are no longer working with the record itself, but a digital photocopy.
Best Practices for Defensible Handoffs
To mitigate these risks, Sauter advocates for a two-pronged strategy:
- Contractual Rigor: Push for structured output requirements in quality agreements. This includes specifying file formats, mandatory metadata fields, version identifiers, and standardized handoff protocols. Even if the CDMO cannot comply immediately, establishing these requirements creates a clear expectation and a legal baseline.
- Receipt-Phase Validation: The moment a document arrives, the system must perform two critical functions:
- Version Locking: Ensuring the received file is immutably recorded to prevent tampering.
- Structure Validation: Ensuring the document is machine-readable and compliant with pre-defined standards before it ever touches an AI model.
By validating at the point of entry, organizations create a "defensible handoff record." This does not replace source-level traceability, but it creates a necessary barrier that ensures the sponsor can prove exactly what they received, when they received it, and in what condition.
The Hidden Risks of AI Transformation
Perhaps the most significant revelation from the discussion was the danger lurking within the AI transformation process itself. When data is "chunked" or "embedded" for use in Large Language Models (LLMs) or retrieval-augmented generation (RAG) systems, the integrity of the original document is often compromised.
The "Chunking" Trap
Sauter identifies this as one of the most underestimated risks in enterprise AI. "Every transformation step between the original document and the AI model is a potential integrity loss," she explained.
Common AI workflows involve breaking large documents into smaller, manageable chunks. If done improperly, this process can lead to:
- Table Fragmentation: Column headers may be separated from their values, rendering the data meaningless or misleading.
- Summarization Bias: Essential evidentiary details—such as lot numbers, qualification records, or specific ranges—are often compressed into general statements that lack the specificity required for regulatory defense.
- Embedding Ambiguity: Converting text into vectors (the numerical format used by AI) risks losing the hierarchical structure and provenance of the information.
The "AI-Ready" Standard
Sauter proposes a higher bar for "AI-readiness." True AI-readiness is not merely digitization; it is the preservation of structure. An AI-ready batch record must have its tables intact, sections labeled, and critical fields validated before any transformation occurs.
When a document is properly structured before being fed into an AI system, the transformation process becomes more reliable. The "chunking" strategy can respect document boundaries, and the "embeddings" can carry essential metadata.
Implications for Regulatory Compliance
The takeaway for quality assurance teams is simple yet demanding: if you cannot explain how an AI arrived at a conclusion, you cannot use that conclusion in a regulatory submission.
The "Golden Test" provided by the panel for any organization evaluating their AI integrity is as follows:
- Can you take an AI output?
- Can you trace it back to a specific chunk of data?
- Can you trace that chunk back to a specific passage in a specific version of a specific document?
- Can you demonstrate that the AI’s interpretation remains faithful to the context of the original document?
If any link in that chain is opaque, the system is fundamentally broken for the purposes of pharmaceutical quality assurance. As regulators continue to increase their oversight of AI in the manufacturing lifecycle, the companies that thrive will be those that view "AI-readiness" not as an IT initiative, but as a core component of their quality management systems.
A Path Forward
The insights provided by Merck and Adlib Software highlight a maturing industry. The "Sensor-to-Decision" gap is no longer just about the technical ability to move data; it is about the governance of that data. As the pharmaceutical industry leans deeper into the era of industrial AI, the emphasis must shift from sheer volume of data to the structural integrity and traceability of every byte.
The session at the Industrial AI Summit 2026 served as a wake-up call for the sector: AI is a powerful tool for efficiency, but it is a liability if the foundational documents are not handled with the same rigor as the drugs themselves. As we look toward the future, the integration of document accuracy layers and strict quality agreements will likely become the standard for any manufacturer wishing to remain compliant in an automated world.
This report is part one of a two-part series based on audience questions from the "You Closed the Sensor-to-Decision Gap. FDA Will Ask You to Explain It" session at the Industrial AI Summit 2026. The session featured insights from Adam Procopio (Merck), Kristen Sauter (Adlib Software), and Maya Schushan-Orgad (Teva Pharmaceuticals), and was moderated by Rick Franzosa (Tech-Clarity).