
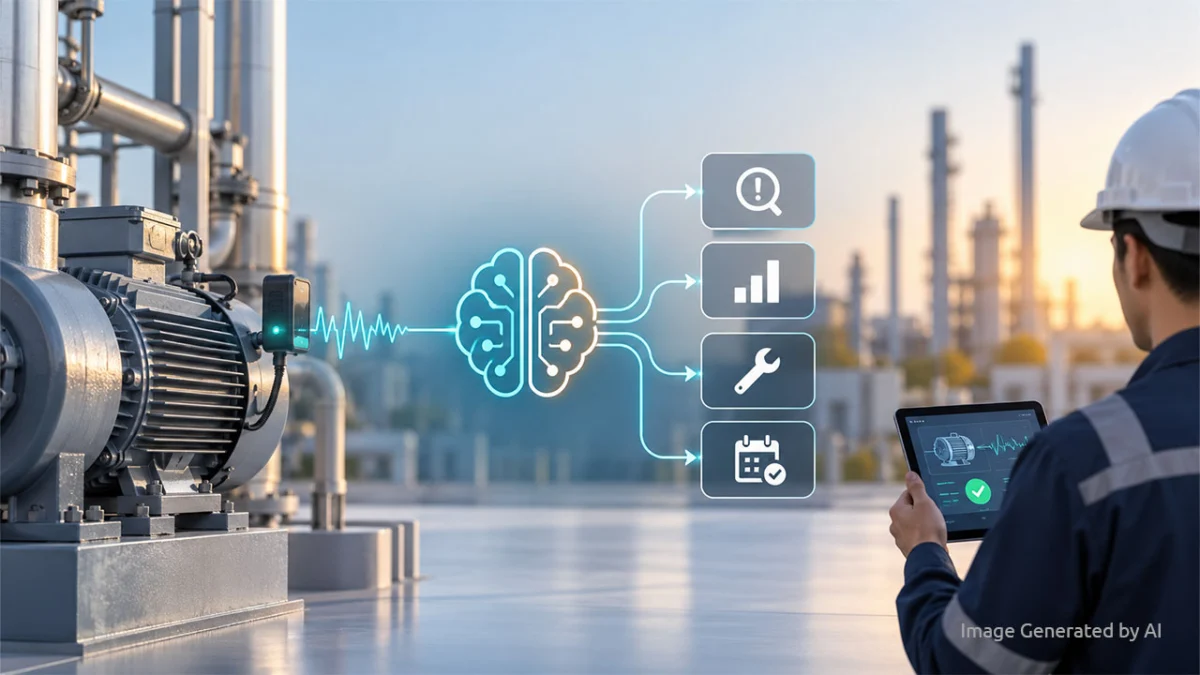
The promise of Industry 4.0 has long been anchored in the concept of "Prescriptive AI"—systems that don’t just warn of an impending failure, but explicitly tell plant operators which components to replace, what specific maintenance actions to take, and precisely when to perform them. However, as the manufacturing sector pivots from theoretical potential to operational deployment, a chasm has emerged between the promise of autonomous reliability and the messy reality of industrial data landscapes.
At the Industrial AI Summit 2026, industry experts Boris Scharinger, author of Industrial AI: From Pilot to Profit and a leader in R&D Excellence and DataOps at Siemens, joined Karthikeyan Natarajan, CEO of Infinite Uptime, to address the skepticism defining current deployments. During the session, "Unlocking Plant Reliability with Verticalized Prescriptive AI," the panelists tackled the hard questions regarding data maturity, the economics of maintenance, and the imperative of building trust in an era of algorithmic decision-making.
The Data Maturity Dilemma: Is AI Ready for the Shop Floor?
A recurring critique in the manufacturing sector is that companies are attempting to implement advanced AI before they have achieved fundamental data hygiene. During the summit, a critical audience question cut to the heart of the matter: "Is Industrial AI really the solution of today, or should we prioritize data management and ‘Industrial Intelligence’ before attempting AI deployment?"
The Ideological Divide
Boris Scharinger identifies this as an "ideological" conflict within corporate hierarchies. "CFOs look at use cases as the lever to pull ROI, while CTOs view a data strategy as a foundational investment in strategic capability," Scharinger noted. He argues that the debate often ignores the "Data Layer," which acts as a foundational capability that cannot be easily shoehorned into the ROI calculation of a single, isolated use case.
The Physics-Aware Alternative
Karthikeyan Natarajan offered a more radical perspective, arguing that waiting for a "clean" data foundation is a "multi-year tax" that most companies cannot afford. He points out that historical data is often sparse, corrupted, or non-existent for aging equipment.
"This is exactly why physics-aware AI beats data-dependent AI," Natarajan explained. By starting with the known physics of an asset and vertical-specific fault patterns, Infinite Uptime’s approach generates clean, structured, and validated data going forward. In this model, data maturity and the intelligence layer are built in parallel, rather than one gating the other. The key, he suggests, is to prioritize by production consequence: start with the highest-consequence, most critical assets to realize immediate value.
Modernizing the Brownfield: The Path from 3.0 to 5.0
For many, the transition from Industry 3.0 to 4.0/5.0 feels like a leap into the unknown. One attendee described their success in retrofitting a track manufacturing plant with cameras for vision and thermal monitoring, essentially giving eyes and temperature sensitivity to legacy milling machines.
The Role of Sensor Retrofitting
Scharinger views this as an ideal strategy for brownfield environments. Retrofitting sensors not only bypasses the need for costly original-equipment-manufacturer (OEM) software upgrades but also strengthens vendor independence.
Natarajan added that combining sensing modalities is essential for full asset visibility. "Vibration monitoring catches mechanical degradation, while vision and thermal sensing catch process-induced and quality-correlated issues that vibration simply cannot see," he noted. By layering these data streams, manufacturers can create a more holistic "asset-reality" profile.
The Diagnostic Hierarchy: From Anomaly to Action
One of the most nuanced debates at the summit concerned the diagnostic approach to maintenance. When should a company use human review, supervised learning, or Large Language Models (LLMs)?
The Sequencing Strategy
Scharinger proposed a phased approach:
- Anomaly Detection: Use as a starting point to alert humans to deviations.
- Classification: Mapping symptoms to specific diagnostic labels.
- Documentation Integration: Leveraging RAG (Retrieval-Augmented Generation) + LLMs to connect identified error types to technical manuals, FAQs, and troubleshooting guides.
Natarajan cautioned against relying on LLMs for diagnostic heavy lifting. "Treating an LLM as the primary engine to detect physical failure modes skips the physics and creates real risk," he warned. Instead, his firm utilizes a human-in-the-loop verification process, where physics-informed signatures generate a prescription, a reliability expert validates it, and the LLM acts purely as an explanation layer to assist the technician.
The Economics of Reliability: To Replace or To Predict?
A fundamental economic question haunts predictive maintenance: Is it cheaper to let a part fail or to predict its failure?
Scharinger admitted there is no universal rule of thumb. The decision depends on a complex calculation involving:
- The cost of unplanned downtime: The primary driver for most industries.
- The cost of "stranded" asset life: If you replace a part early, you are sacrificing its remaining useful life.
- The cost of intervention: Labor and planned downtime expenses.
Scharinger recommends building a quantitative decision model for each specific use case, perhaps even utilizing Monte Carlo simulations to account for the inherent uncertainties of machine performance.
The "Invisible" Cost of Algorithmic Auditing
A provocative question from the floor asked: "Was the cost of the internal audit on the algorithms calculated?"
Scharinger provided a rare window into the resource intensity of enterprise AI. He noted that while internal costs might not be cross-charged to business units, a rigorous audit—involving defining risk assessment approaches, validating business assumptions, and running simulations—is typically a 2-to-3-person, 6-week effort. This reinforces the idea that AI is not a "set-and-forget" technology, but an enterprise asset that requires ongoing stewardship.
Trust, Security, and the "Audit-Ready" Future
As manufacturers increasingly use tools like Microsoft Copilot or Claude for internal knowledge management, the question of proprietary data security becomes existential.
Scharinger’s advice was clear: "You must negotiate a contract that explicitly forbids the provider from using your data for model training, or migrate to a private, corporate-managed environment like Azure OpenAI Services."
Building Trust Through Rigor
Perhaps the most significant challenge discussed was whether AI data passes the same quality rigor as a physical product. The panel agreed that most organizations currently lack this level of discipline.
"If your AI makes decisions based on data that hasn’t passed the same quality rigor you’d apply to a physical component, is that AI trustworthy, or is it just fast?" the moderator asked.
Natarajan concluded that true trust is forged in a "closed loop." By ensuring that every prescription is verified by a human expert and that the real-world outcome is fed back into the system, organizations can move beyond mere speed. For the industrial sector, the future of AI is not about replacing the human element, but about creating an audit-ready, physics-validated system where the "intelligence" is as reliable as the machinery it monitors.
This report is based on the "Unlocking Plant Reliability with Verticalized Prescriptive AI" session at the Industrial AI Summit 2026. Panelists included Boris Scharinger (Siemens) and Karthikeyan Natarajan (Infinite Uptime), with contributions from Jan Pingel (Ingersoll Rand) and moderation by Rob Tiffany (IDC).