In the high-stakes world of pharmaceutical manufacturing, a single question from a regulatory agency—such as the FDA or the EMA—can trigger a month-long investigative scramble. Regulatory response teams often spend 30 days or more simply locating the documents necessary to satisfy a single inquiry. This administrative bottleneck is not merely a matter of inefficiency; it is a fundamental breakdown in data architecture.
At the Industrial AI Summit 2026, industry leaders from Merck, Teva Pharmaceuticals, and Adlib Software converged to discuss a critical inflection point: the friction between legacy document management and the burgeoning promise of Agentic AI. The core of the problem lies in the "PDF-ification" of critical batch records as they move from Contract Development and Manufacturing Organizations (CDMOs) to the pharmaceutical sponsors who hold the ultimate regulatory burden.
The Main Facts: The "Unknown Knowns" of Pharma Data
The fundamental challenge, as articulated by Adam Procopio, Scientific Associate Vice President at Merck, is the existence of "unknown knowns." These are data points that reside somewhere within the vast enterprise ecosystem but remain functionally invisible to AI agents and human auditors alike.
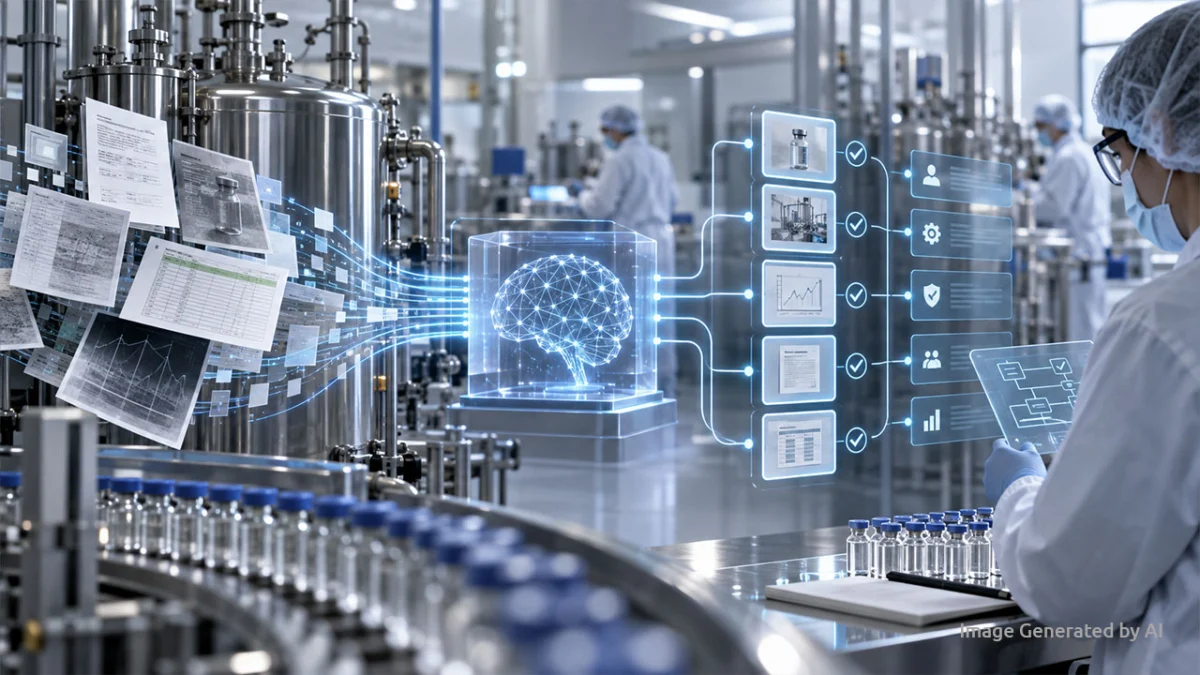
When a CDMO runs an electronic batch record (eBR), the internal data is typically granular, structured, and machine-readable. It contains precise sensor-level values, timestamps, and process parameters. However, as soon as this information is transferred to a pharmaceutical company’s system, it is frequently converted into a static PDF. In this transformation, the metadata, logical relationships, and structural context are stripped away.
While the human eye can read a PDF, an AI agent—which requires structured data to perform complex traceability and decision-tracking—cannot. Consequently, when auditors request a breakdown of a specific process deviation or quality control event, the pharmaceutical company is forced to manually piece together fragmented spreadsheets, scanned images, and flat documents. The "structure" that once existed at the point of origin is sacrificed at the altar of file compatibility.
Chronology of a Compliance Breakdown
The lifecycle of a document in modern pharma is increasingly fragmented. To understand the current crisis, one must look at the progression of data interaction:
- Generation: A CDMO captures real-time sensor data, system logs, and operator inputs into a secure, structured digital environment.
- Transmission: The data is exported for the pharmaceutical partner. In the interest of "universal readability," the system exports the data into a PDF or a non-standardized flat file.
- Ingestion: The pharmaceutical company receives the file. The original machine-readable structure is lost. The information is now "trapped" in an unstructured format.
- The Inquiry: A regulator requests data regarding a specific batch. The pharmaceutical company must spend weeks manually searching, extracting, and re-validating the data contained within thousands of disparate documents.
- The Failure: Because the data was not maintained in a structured format, the AI tools intended to automate compliance and traceability fail, as they cannot map the current data back to its raw, source-level origin.
Maya Schushan-Orgad, Senior Director and Open Innovation Platform Lead at Teva Pharmaceuticals, highlights that this problem is compounded by the extreme heterogeneity of manufacturing sites. Across global supply chains, machines from different eras and manufacturers produce data in incompatible formats. Integrating these diverse silos into a cohesive, AI-ready architecture is the defining challenge of the current decade.
The Accountability Gap: Outsourcing Work, Not Responsibility
Perhaps the most significant regulatory hurdle is the principle of non-delegable accountability. Pharmaceutical companies may outsource the manufacturing process to CDMOs, but they cannot outsource the regulatory responsibility for the product’s quality dossier.
As Adam Procopio noted during the panel: "We can outsource the work. We can’t outsource accountability."
Regulators expect the pharmaceutical company to maintain total integrity over every document backing a filing. If an external partner provides a non-readable PDF, the pharmaceutical company is still legally responsible for the validity of the data within it. This forces firms to adopt a massive, labor-intensive data normalization process. They must ingest, clean, and convert thousands of legacy-style documents into a standardized schema that their internal AI systems can query, reference, and cite.
Until recently, this was considered an "insurmountable task." However, the panel consensus suggests that the arrival of Agentic AI has shifted the economic and technical calculation. Modern AI agents are capable of autonomously navigating, parsing, and restructuring unstructured data at scale. The barrier is no longer technical capability, but rather the willingness of the organization to invest in the computational tokens and infrastructure required to "re-structure" the enterprise.
Official Responses and Industry Guidance
The regulatory landscape is shifting to meet these technological realities. The FDA’s recent guidance on AI in regulatory decision-making has been widely analyzed, but industry experts caution against viewing it as a comprehensive manual.
According to Kristen Sauter, President and General Manager of Life Sciences at Adlib Software, the FDA’s guidance is a "signal that the agency is open to discuss AI utilization," rather than a prescriptive blueprint for implementation. Companies that treat the guidance as a "how-to" manual may miss the underlying message: regulators are moving toward data-driven, rather than document-driven, submissions.
The shift is clear: regulators are tired of reviewing PDFs. They are increasingly demanding the raw, structured data that informs the summaries. For pharmaceutical firms, this means the current practice of maintaining "paper-on-glass" (PDFs) is a liability that will only grow in the coming years.
Implications: To Reconstruct or to Pivot?
A recurring question posed to the panel was whether companies should attempt to reconstruct their existing, messy, unstructured document archives or simply start fresh.
The answer from Adlib’s leadership was stark: "Don’t do it."
The consensus is that attempting to retroactively apply structure to a decade of legacy data is a futile, indefensible, and astronomically expensive endeavor. Instead, companies should focus on a "work-forward" strategy. By implementing structured data capture at the source—today—organizations can ensure that future filings meet the rigorous, data-driven standards of tomorrow’s regulators.
Strategic Recommendations:
- Prioritize Data at the Point of Origin: Shift focus away from document management and toward data lifecycle management. Ensure that CDMO agreements require the delivery of structured, machine-readable data alongside (or instead of) static PDFs.
- Adopt Agentic AI for Ingestion: Rather than manual data entry, leverage AI agents to process incoming partner data, automatically mapping it to internal schemas.
- Accept the Sunk Cost: Recognize that the archive is a static record of a bygone era. Focus investment on ensuring that current and future production cycles are natively "AI-traceable."
- Engage Regulators Proactively: Use the current window of regulatory openness to establish how your company intends to handle data provenance, rather than waiting for an audit to expose the gaps in your traceability.
Conclusion
The pharmaceutical industry stands at a crossroads. The reliance on PDF-based documentation is a relic of the pre-AI era that now acts as a primary barrier to compliance efficiency and operational intelligence. By shifting the focus from "document archiving" to "structured data integrity," pharmaceutical firms can move away from the expensive, 30-day manual search cycles and toward a future where compliance is a real-time, automated function of their manufacturing operations.
As the industry moves toward 2026 and beyond, the companies that thrive will be those that accept that while they may outsource the labor of manufacturing, they must own the architecture of the data that defines their products. The path forward is not found in the archives of the past, but in the rigorous, structured digital pipelines of the future.