The transition from traditional data science to the age of autonomous AI agents marks a fundamental shift in how manufacturing organizations manage their information infrastructure. Historically, data quality was a "human-in-the-loop" exercise: data scientists cleaned inputs, validated models, and manually curated datasets to ensure reliability. Today, that luxury has vanished. AI agents now consume and act upon data at machine speed, often without human oversight to correct errors or mitigate biases.
This paradigm shift was the central theme of a high-level panel discussion hosted by IIoT World in December 2025. Experts from Michelin, ATELIC, Körber Pharma, and 4D1 argued that organizations must move beyond the basic pursuit of "clean" data and embrace a framework known as Cognitive Data Readiness.
Main Facts: The New Frontier of Industrial Intelligence
At the core of the current industrial challenge is a disconnect between legacy operational technology (OT) and the high-velocity requirements of AI agents. According to a poll conducted during the IIoT World session, 37% of manufacturers identified siloed OT data as their primary barrier to achieving "trusted AI."
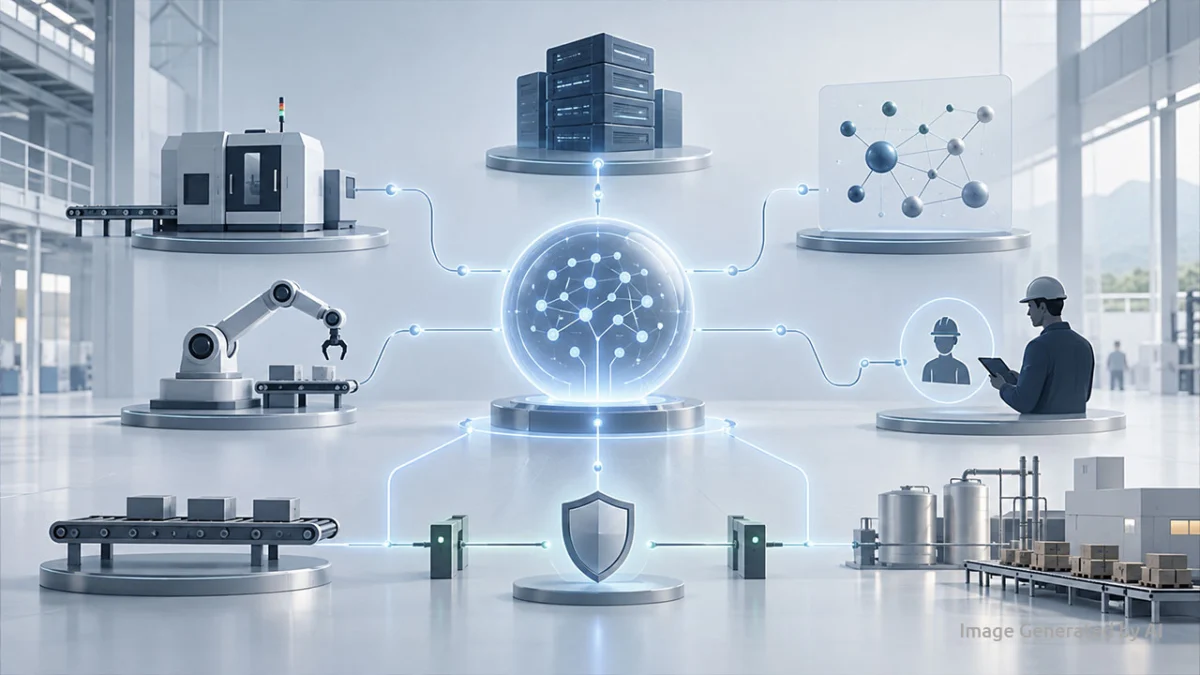
Cognitive data readiness is a multi-layered architecture designed to bridge this gap. It goes beyond mere contextualization—the process of linking IT and OT data—to encode causal relationships, governance constraints, and operational tradeoffs directly into the data stream. By doing so, it allows AI agents not just to identify patterns, but to reason through complex, real-world manufacturing decisions.
The problem, however, remains systemic. The same survey revealed that 30% of manufacturers struggle with legacy systems characterized by inconsistent data formats, while 22% cite insufficient governance policies. These issues are self-reinforcing: data silos inevitably lead to format inconsistencies, which in turn make the implementation of unified governance nearly impossible.
Chronology: The Evolution of Industrial Data Management
To understand the current crisis, one must look at the evolution of industrial data:
- The Pre-AI Era (2000–2015): Manufacturers focused on siloed automation. Processes were optimized individually, leading to pockets of high efficiency but a fragmented digital landscape.
- The Data Lake Era (2015–2022): The focus shifted to "big data." Organizations attempted to consolidate information into central repositories, often resulting in "data swamps" where quality was sacrificed for volume.
- The Agentic AI Transition (2023–Present): The rise of autonomous agents has exposed the limitations of traditional data architectures. Because these agents operate in milliseconds, traditional, human-led data quality control processes have become the primary bottleneck to production-scale AI.
Supporting Data: The Anatomy of Readiness
Passing a standard data quality scorecard—completeness, accuracy, consistency, and visibility—is no longer the benchmark for success. Today’s requirements include stability and reproducibility.
The Stability Challenge
Data drift—the phenomenon where the statistical properties of data change between the training phase and the production phase—is a silent killer of AI performance. If training data is biased or incomplete, the model will inevitably fail when it encounters edge cases on the factory floor. Furthermore, the features utilized during the training cycle must be perfectly reproducible in real-time production. When offline training pipelines diverge from online operational pipelines, model behavior becomes unpredictable and potentially hazardous.
The Governance Bottleneck
Governance has long suffered from a "reputation problem." Historically, it has relied on manual approvals, complex committees, and static PDF documentation—all of which operate at human speed. When faced with AI agents making decisions in milliseconds, traditional governance models are effectively rendered obsolete.
The industry is now pivoting toward "Minimum Viable Governance." Instead of monitoring forty disparate metrics, experts suggest focusing on five to seven key performance indicators (KPIs) that can be embedded directly into the data pipeline. By automating approximately 80% of governance checks, organizations can ensure that compliance, drift monitoring, and anomaly detection occur at the speed of the data itself.
Official Perspectives: Expert Insights from the Frontlines
The panel discussion featured insights from leaders at the forefront of digital transformation:
- Romina Guevara (formerly of Michelin): Emphasized that the challenge is not just technical but structural. Organizations have spent decades optimizing processes in isolation, and the current goal is to transform those pockets of harmonization into a singular, connected digital twin.
- Dr. Judith Koliwer (Körber Pharma): Provided a stark warning based on FDA observations. She noted that a majority of clinical trial failures are linked to data integrity issues. In the pharma sector, poor data quality directly impacts patient outcomes; in manufacturing, it creates cascading financial and operational failures.
- Douglas Langen (4D1): Highlighted the importance of "ground truth." He noted that reconciling logical Manufacturing Execution System (MES) data with physical reality—using real-time location systems with millimeter-level accuracy—is the only way to provide AI with a verified foundation for decision-making.
- Dr. Omid Givehchi (ATELIC): Advocated for the integration of governance into the code itself. "Policy-as-code" is the future of agentic platforms, replacing manual spreadsheets with continuous, autonomous risk analysis.
Implications: Building for the Future
For manufacturers looking to move from pilot programs to production-scale AI, the road map is clear:
1. Start with In-Development Processes
Counter-intuitively, experts suggest beginning with processes still in development. Mature processes are often too rigid. In contrast, new processes introduce the type of controlled variation that builds robust characterization data. This allows AI models to learn from a diverse range of conditions, improving their generalization capabilities.
2. Prioritize User Adoption
A common failure point is forcing operators to become "data clerks." If a solution requires an operator to close one system and open another just to input data, adoption will inevitably stall. The goal must be to embed data enrichment tools directly into the workflow, providing value in the moment rather than creating additional administrative burdens.
3. Embrace Policy-as-Code
Governance should function like a security operations center (SOC). Just as cyber threats are countered by automated, high-speed security software, AI agents must be governed by an "AI for AI" layer. This layer monitors, controls, and intervenes in agent behavior without requiring a human to review every single decision.
Conclusion: The Path to Cognitive Maturity
The journey to Cognitive Data Readiness is a shift from reactive data cleaning to proactive data architecture. It requires manufacturers to acknowledge that their historical focus on individual process optimization has created a significant hurdle for modern AI.
By integrating physical sensor data with contextual IT/OT bridges and adding a layer of cognitive governance, manufacturers can finally unlock the potential of autonomous agents. The difference between a model that works in a demo and one that operates reliably on a production line is no longer just "clean data"—it is the ability to encode the complexity of the factory floor into the very DNA of the AI’s decision-making engine. As the industry looks toward 2027 and beyond, those who prioritize this cognitive layer will be the ones who define the future of the industrial landscape.