At the Industrial AI Summit 2026, a critical session titled "You Closed the Sensor-to-Decision Gap. FDA Will Ask You to Explain It" highlighted a growing tension in the pharmaceutical industry: as manufacturers accelerate the deployment of Artificial Intelligence, they are uncovering deep-seated vulnerabilities in how they manage and validate their foundational documentation.
While the session provided a roadmap for sensor-driven decision-making, the aftermath revealed a flurry of unanswered questions regarding document integrity, particularly when dealing with third-party Contract Development and Manufacturing Organizations (CDMOs). To address these concerns, Adam Procopio, Scientific Associate Vice President at Merck, and Kristen Sauter, President and General Manager of Life Sciences at Adlib Software, have provided in-depth insights into the operational and technical realities of maintaining "audit-ready" data pipelines.
The Core Challenge: Data Integrity Across Fragmented Ecosystems
The pharmaceutical industry relies on a complex web of partnerships. When a sponsor company like Merck outsources production to a CDMO, the "document chain of custody" is frequently disrupted. The audience at the Industrial AI Summit posed a direct, challenging question to the panel: Do you force CDMOs to adhere to rigid document standards, or do you accept the reality of heterogeneous data and absorb the remediation burden internally?
The "Prevention vs. Remediation" Dilemma
For Adam Procopio of Merck, the preference is clear: "We certainly want to push digital data requirements into our quality and technical agreements whenever possible because prevention is better than remediation." However, Procopio admits that the ideal scenario—where every partner delivers perfectly structured, machine-readable data—is rarely the reality.
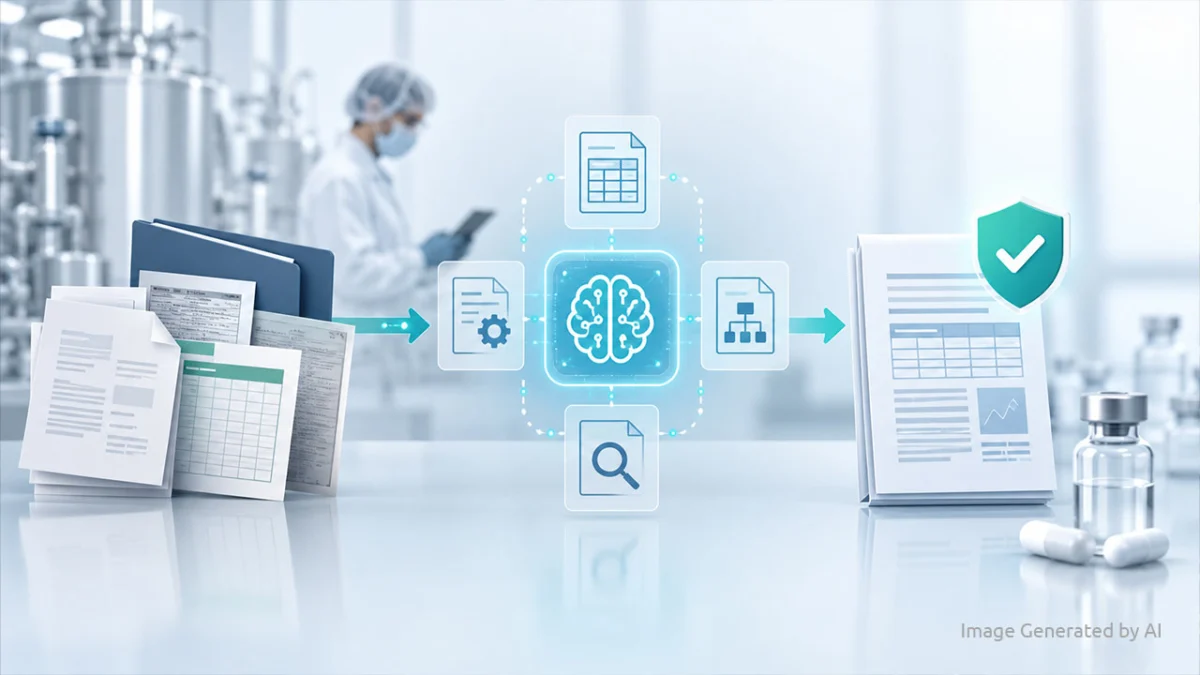
The industry operates across a spectrum of digital maturity. Forcing a rigid standard on a partner with legacy systems can stifle progress. "We cannot wait for every partner to produce perfectly structured data before we gain value from AI," Procopio noted. Consequently, the strategy shifts toward "ingestion resilience." Organizations must deploy technology capable of normalizing spreadsheets, scanned records, and fragmented PDFs while maintaining a strict, auditable link back to the original document.
The Role of the "Accuracy Layer"
Kristen Sauter of Adlib Software emphasizes that the gap between a raw PDF and an AI-ready document is a specific technical hurdle that requires an "accuracy layer." This layer is not merely about digitizing text; it is about providing a transparent, auditable history of the data’s transformation.
"The key architectural requirement is that the transformation from whatever format you receive to a normalized, AI-ready output must itself be auditable," Sauter explained. "You need to be able to show: here is what we received, here is what the system did to it, here is what entered the AI workflow, and here is the confidence score on the extraction."
Chronology of the Document Lifecycle: When Does Traceability Begin?
A recurring debate in the life sciences sector concerns the starting point of traceability. Should it begin at the generation of the document at the CDMO, or at the moment of receipt by the sponsor?
The Failure of Retroactive Traceability
Sauter argues that "build it at the source" is the gold standard, but it is notoriously difficult to implement. When a batch record crosses the boundary from a CDMO to a sponsor, the context is often stripped away. Metadata—the "DNA" of the record—is lost, leaving the sponsor to work with a "copy of a copy."
"Traceability retrofitted at receipt is always incomplete," Sauter warned. To mitigate this, she proposes a two-pronged strategy:
- Contractual Enforcement: Even if partners resist, sponsors must mandate file formats, metadata fields, version identifiers, and specific handoff protocols within quality and technical agreements.
- Boundary Processing: Upon receipt, the sponsor’s system must perform two critical, automated actions: lock the version (to create an immutable record) and validate the structure (to determine if the document is processable or requires remediation).
Creating a Defensible Handoff
By validating at the moment of receipt, organizations create a "defensible handoff record." This does not replace source-level traceability, but it creates a verifiable checkpoint that satisfies regulatory scrutiny. The primary failure point remains the "black box" where documents are transformed—chunked, embedded, or normalized—without a corresponding audit trail, leaving a gap that regulators will inevitably probe during audits.
Supporting Data: Why AI Transformation Introduces Integrity Risks
The question of whether the transformation of documents into "AI context" introduces new risks is perhaps the most pressing technical concern for 2026. As AI models require vectorized data to function, the act of "preprocessing" becomes a point of potential failure.
The Risks of Data Preprocessing
Kristen Sauter identifies several common transformation steps that, if mishandled, can lead to compliance disasters:
- Chunking: The process of breaking large documents into smaller segments for the AI to process. If tables are split across chunks, headers may become detached from their values, rendering the data misleading or nonsensical.
- Summarization: When AI condenses evidentiary detail into a summary, it risks losing critical qualifiers—such as lot numbers, specific range limitations, or reviewer credentials—that are essential for proving compliance.
- Embedding: Converting meaning into mathematical vectors for searchability. The risk here is that the AI may prioritize "similarity" over "authority," potentially elevating an outdated or non-authoritative version of a document simply because it shares similar phrasing.
Defining "AI-Ready"
Sauter draws a firm line between "digitized" and "AI-ready." A scanned batch record is merely digitized; it lacks structure. An "AI-ready" record, by contrast, has its tables intact, its sections labeled, and its provenance locked. When the document is already structured, the AI’s chunking strategy can respect logical boundaries rather than imposing arbitrary, potentially harmful cuts.
Official Industry Stance: The Path Forward
The discussion at the Industrial AI Summit 2026 suggests that the pharmaceutical industry is moving away from a "wait and see" approach toward a more proactive, governance-heavy framework for AI.
The Emerging Regulatory Expectation
The session, moderated by Rick Franzosa of Tech-Clarity and featuring insights from industry veterans like Maya Schushan-Orgad of Teva Pharmaceuticals, underscores a unified realization: If you cannot explain how your AI reached a conclusion, you cannot use it in a regulated environment.
Procopio identified the current "gaps" in the industry as follows:
- Semantic Interpretation: AI still struggles to understand the meaning behind complex pharmaceutical technical language.
- Cross-Document Reasoning: The ability to synthesize information across disparate documents remains inconsistent.
- Explainability: Generating conclusions that are defensible under strict FDA scrutiny remains the "holy grail" of industrial AI.
Implications for Future Strategy
For organizations looking to deploy AI successfully, the strategy is shifting toward:
- Normalization at Ingestion: Reducing the "failure surface" by ensuring that, even if data comes in messy, it is cleaned and structured at the earliest possible moment.
- Audit-First Architecture: Treating the AI’s data pipeline as a validated system. Every step of the transformation—from the original PDF to the vector database—must have a clear, reproducible log.
- The "Traceability Test": Sauter proposes a simple litmus test for any AI deployment: Can you take an AI output, trace it to a specific chunk, trace that chunk to a specific passage in a specific document version, and verify the context? If the answer is no, the process is not yet ready for production.
Conclusion: Bridging the Gap
The transition to an AI-driven pharmaceutical landscape is not merely a software integration challenge; it is a fundamental transformation of document governance. As Adam Procopio and Kristen Sauter illustrated, the "sensor-to-decision" gap can only be bridged when the documentation backing those decisions is as robust, transparent, and immutable as the physical manufacturing processes themselves. As regulators sharpen their focus on the "black box" of AI, the winners will be the organizations that prioritize the integrity of the data pipeline over the speed of the AI deployment.
This article is part one of a two-part series based on audience inquiries from the "You Closed the Sensor-to-Decision Gap. FDA Will Ask You to Explain It" session at the Industrial AI Summit 2026. The session was sponsored by Adlib Software.