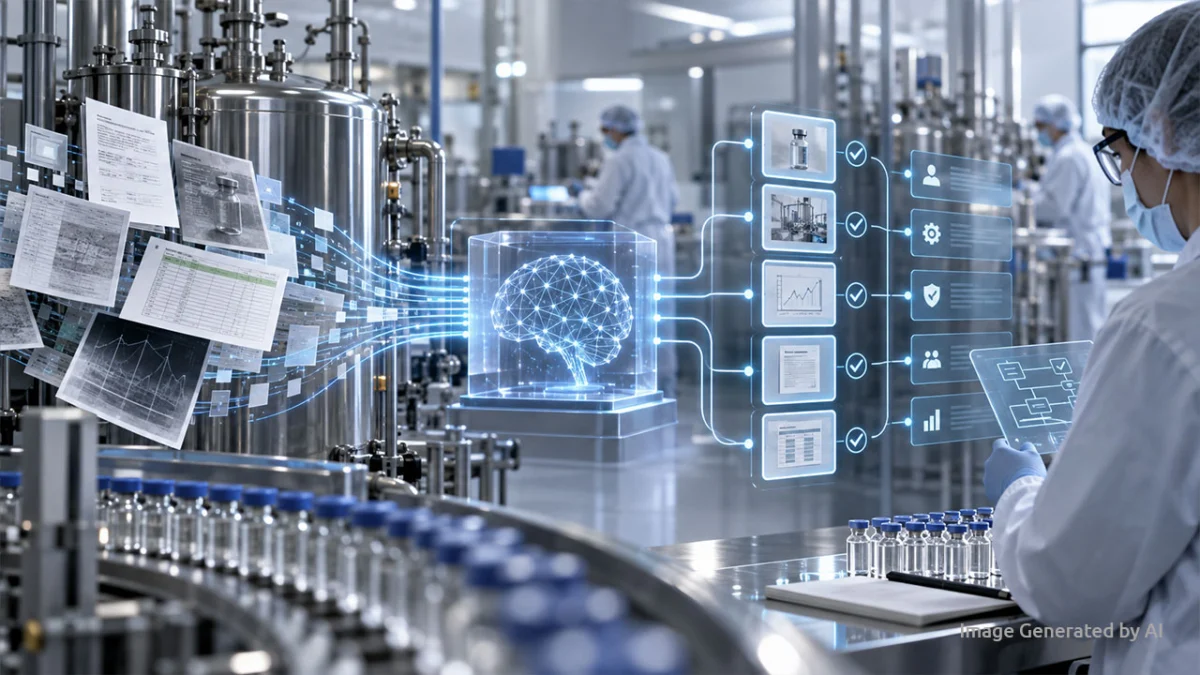
In the high-stakes world of pharmaceutical manufacturing, a single inquiry from a regulatory agency—such as the FDA or the EMA—can trigger a 30-day "all hands on deck" scramble. For many companies, the majority of this month-long effort is not spent on scientific analysis, but on a digital scavenger hunt: searching for documents buried in disparate silos to prove the integrity of a batch record.
At the Industrial AI Summit 2026, industry leaders converged to address this systemic bottleneck. Kristen Sauter, President and General Manager of Life Sciences at Adlib Software, and Adam Procopio, Scientific Associate Vice President at Merck, highlighted a fundamental flaw in the industry’s digital infrastructure. Every time a contract development and manufacturing organization (CDMO) transfers an electronic batch record to a pharmaceutical sponsor, the data is stripped of its machine-readable structure, arriving as a static, “flat” PDF. This transformation renders the data effectively invisible to the very AI systems designed to manage compliance and quality control.
The Chronology of Data Decay
The crisis begins at the point of origin. A CDMO typically manages its production floor using sophisticated electronic batch record (EBR) systems that capture high-fidelity, sensor-level data in a structured, digital format. This data is the lifeblood of quality assurance. However, the current standard for data exchange between manufacturing partners and pharmaceutical sponsors is fundamentally archaic.
When the CDMO exports this record, it is converted into a PDF—a "digital piece of paper." This format is designed for human eyes, not for algorithmic ingestion. Once this PDF crosses the firewall into the pharmaceutical company’s ecosystem, the granular, structured data—the timestamps, the sensor values, the precise calibration logs—is locked inside an image or unstructured text.
As the number of system interactions between partners increases, the problem scales exponentially. Each handshake between a CDMO and a pharmaceutical sponsor regenerates documents in a way that discards metadata. This creates what Adam Procopio describes as the industry’s "unknown knowns": vast repositories of data that exist somewhere within the enterprise, but are functionally inaccessible to AI, auditors, and even internal quality teams.
The Complexity of Heterogeneity
The problem is further compounded by the lack of standardization across the manufacturing landscape. Maya Schushan-Orgad, Senior Director and Open Innovation Platform Lead at Teva Pharmaceuticals, pointed out during the summit that the heterogeneity of manufacturing sites—each utilizing different machines, software suites, and legacy formats—creates a fractured digital landscape.
When a pharmaceutical company aggregates data from multiple global sites, they are effectively trying to build a cohesive narrative from thousands of different dialects. This lack of interoperability forces teams to engage in manual data cleansing and transformation, which is not only slow but introduces the risk of human error—the very thing regulatory frameworks aim to eliminate.
Who Owns the Integrity of Outsourced Data?
A central theme of the summit was the inescapable nature of regulatory accountability. While pharmaceutical companies frequently outsource the physical act of manufacturing to CDMOs, they cannot outsource their regulatory responsibility.
"We can outsource the work. We can’t outsource accountability," Procopio noted.
Regulatory agencies expect the pharmaceutical sponsor to maintain complete integrity of the data behind every filing. If an issue arises, the sponsor must be able to trace a decision back to the source data, even if that data was generated in a partner’s facility thousands of miles away.
Currently, this creates a massive operational burden. Pharmaceutical companies must ingest fragmented spreadsheets, scanned logs, and non-readable PDFs from a variety of external sources, then manually convert them into a schema that their internal AI systems can reference. This process is, by definition, reactive and fragile. For years, the industry viewed the task of structuring decades of legacy data as an insurmountable mountain. However, the emergence of agentic AI—systems capable of performing complex, multi-step reasoning tasks—has shifted the calculus. For organizations willing to invest in the computational resources, or "tokens," required, the automation of this ingestion process is no longer a pipe dream; it is a current reality.
The Strategic Dilemma: Fixing the Past vs. Investing in the Future
One of the most contentious debates in pharmaceutical digital transformation is whether companies should spend resources retroactively structuring their existing archives or focus exclusively on modernizing future data flows.
Adlib’s stance is firm: Do not try to fix the archive.
The effort required to reconstruct traceability for decades of unstructured, legacy data is rarely defensible from a return-on-investment (ROI) perspective. Moreover, the goalposts for regulatory compliance are moving. Health authorities are aggressively shifting toward data-driven, digital-first submissions. Spending resources on a backlog that predates these modern requirements is effectively a sunk-cost fallacy.
Instead, companies are advised to "work forward." By building traceability at the source—ensuring that every new batch record is created in a structured, AI-ready format from the moment of inception—manufacturers can align themselves with the future of regulatory scrutiny. Reconstructing the past is a bottomless pit; building for the future is a strategic imperative.
Implications for AI and Regulatory Compliance
The FDA’s recent guidance on the use of AI in regulatory decision-making is often misinterpreted as a prescriptive manual for implementation. Industry experts warn that companies should view the guidance as a signal of openness rather than a blueprint. The agency is signaling that they are prepared to discuss AI-driven compliance, but the burden of proof remains squarely on the manufacturer.
For companies currently calibrating their AI strategy, the implications are clear:
- Prioritize Data Quality at the Source: If the input is a PDF, the AI output will be flawed. Investing in structured data exchange with partners is the highest-leverage activity a pharma company can undertake.
- Embrace Agentic Workflows: Moving away from human-in-the-loop data entry toward AI agents that can classify, extract, and map data will reduce the 30-day inquiry response time to a matter of hours.
- Regulatory Transparency: Engage with regulators early. The shift toward AI-driven compliance is a collaborative evolution. Showing that a company has a robust, data-first strategy is a strong indicator of "quality by design" to health authorities.
Conclusion: The Path Forward
The "unknown knowns" problem is a relic of an era where documents were the primary vehicle for information. As pharma pivots to a data-centric model, the industry must shed its reliance on static PDFs. The technology to bridge the gap between CDMOs and sponsors exists today in the form of agentic AI and robust data schema management.
As demonstrated at the Industrial AI Summit 2026, the question is no longer about whether the technology works, but whether organizations have the discipline to stop "doing it the old way." By refusing to be held hostage by legacy archives and focusing on the digital integrity of current and future manufacturing cycles, pharmaceutical companies can turn their data from a liability into their most powerful regulatory asset.
This article is based on a panel discussion at the Industrial AI Summit 2026 featuring Adam Procopio of Merck, Kristen Sauter of Adlib Software, and Maya Schushan-Orgad of Teva Pharmaceuticals, moderated by Rick Franzosa of Tech-Clarity. AI tools were used to help summarize and organize the content. Reviewed and edited by the IIoT World editorial team.